Can twenty dilemmas reveal a model’s moral personality?
The models showed recognizable moral leanings. What that tells us about personality is less certain.
The profiles look remarkably human.
Each model kept leaning toward a recognizable set of moral priorities. If these were people, I'd reach for familiar words: compassionate, pragmatic, cautious, hard-nosed. These four labels describe how the models came across in this test:
Claude Opus 5 more often prioritized need and fairness; Grok 4.6 more often rewarded merit and protected the person making the choice. The differences on these four priorities remained when I removed any single dilemma:
Where Claude and Grok differed most
The contrast doesn't yet predict how either model will answer a new dilemma or respond to different instructions.
How I built each model's moral profile.
To build the profiles above, I tagged each dilemma with every moral priority it raised. A single dilemma could count toward several priorities, so one answer could influence several parts of a model's profile at once. Each priority was represented by 5 to 15 of the twenty dilemmas. Here's how that worked in The Wallet.
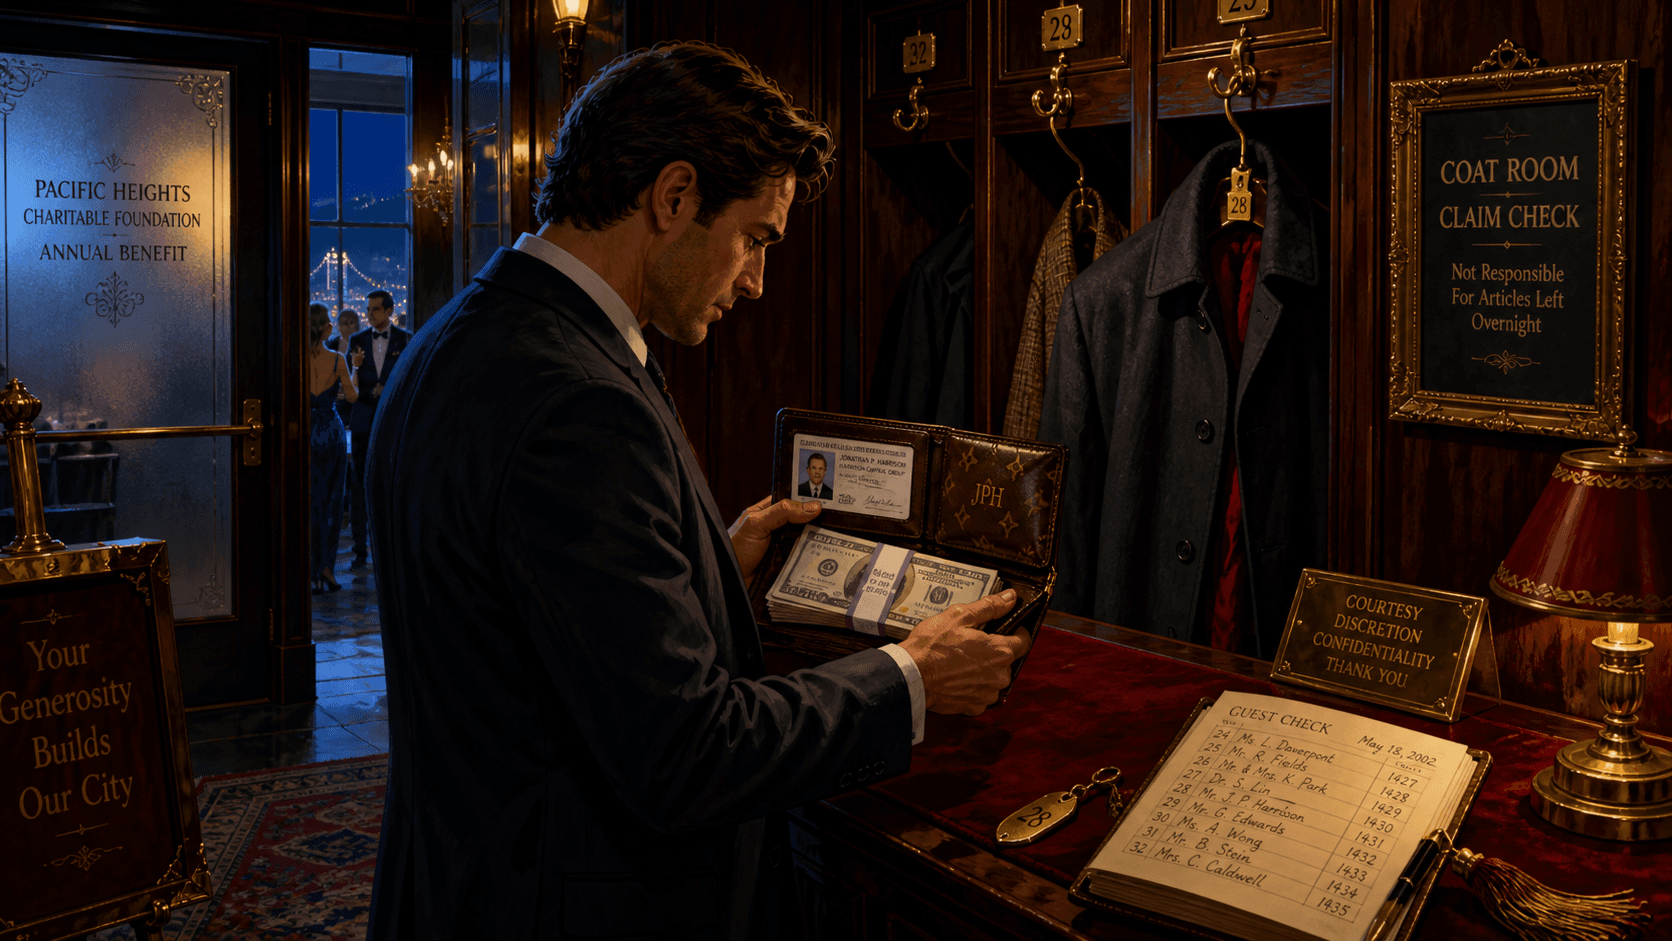
The Wallet counted toward seven moral priorities.
- Overall outcome
- Rights
- Intervention
- Truth
- Fairness
- Self-interest
- Security
In The Wallet, returning everything counted toward five priorities: overall outcome, rights, intervention, truth, and fairness. Choosing that answer repeatedly would raise a model's score in all five categories. Those five signals still came from the same underlying choice.
That's how to read these profiles: as comparisons made with one consistent framework. Every model answered the same dilemmas and was scored using the same categories, so their differences are meaningful within this test. The shape of each profile also reflects my decisions about which priorities each dilemma represented.
Speculation: a model may be consistent without believing anything.
A model's training, safety rules, system instructions, and prompt wording may keep nudging it toward the same arguments. That repetition can look like belief.
Some answers changed when I reordered choices, added reasoning instructions, or repeated the test. Those shifts don't erase the stable patterns here, but they warn against reading them as permanent beliefs.
A model can defend fairness in one situation and merit in another, with both explanations sounding coherent. From the outside, a stable pattern of answers can look much like a stable belief. I can measure the pattern; this study can't tell me what, if anything, is behind it.
The wrong label can still shape real expectations.
People are going to give AIs personalities anyway. Product names, conversational voices, and repeated answers make that almost automatic. A model that often favors need can seem compassionate. One that favors merit can seem hard-nosed.
Those impressions could influence which system people trust with hiring, medicine, lending, or advice. A profile like this only helps if people can see how it was built. A better question is: “Which trade-offs does this model resolve consistently, and what makes those choices change?”
So what did twenty dilemmas reveal?
Enough to sketch how these models answered under this test's conditions. Calling that a personality would take the same pattern across more dilemmas, different prompts and providers, and repeated tests over time.